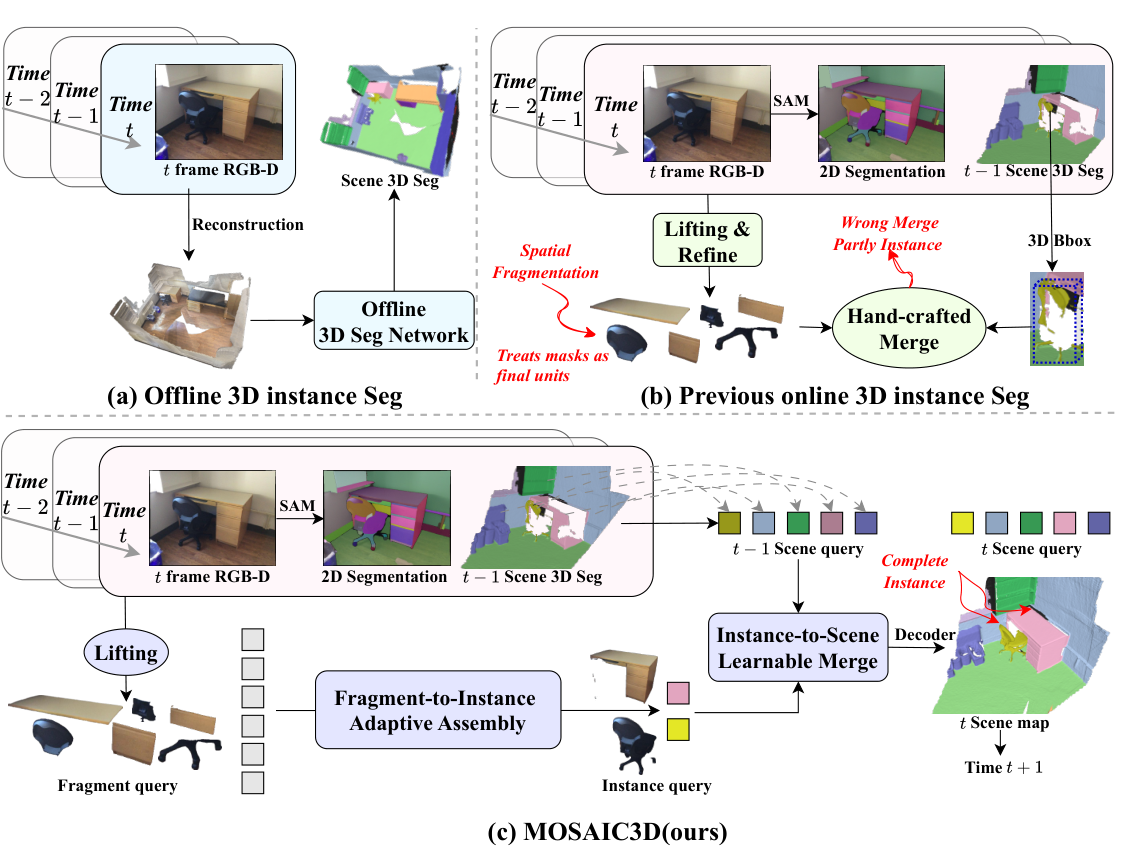
Online 3D instance segmentation is a critical capability for embodied agents navigating in dynamic environments. However, a fundamental challenge remains in adapting powerful 2D foundation models, like SAM, to 3D online segmentation. Naively lifting SAM's 2D masks to 3D results in severe spatial fragmentation, where a single object is shattered into multiple disconnected parts, especially under occlusion. Subsequent attempts to link these fragments over time via conventional 3D IoU-based tracking prove highly fragile: they struggle to handle occlusions or topological changes, ultimately causing catastrophic identity drift. Departing from such post-processing approaches, we reframe online segmentation as a learnable composition problem. We introduce SAMosaic3D, a differentiable framework that treats SAM-derived masks as "mosaic tiles" and learns to assemble them into temporally consistent 3D instances. SAMosaic3D comprises two key components: Fragment-to-Instance Adaptive Assembly that aggregates fragments through soft-gated attention, and Instance-to-Scene Online Merging that employs cascaded semantic-geometric matching to preserve object identities—replacing rigid IoU thresholds with learnable association guided by observation maturity. Evaluations on ScanNet, ScanNet200, SceneNN and 3RScan datasets demonstrate state-of-the-art performance and zero-shot cross-dataset generalization.
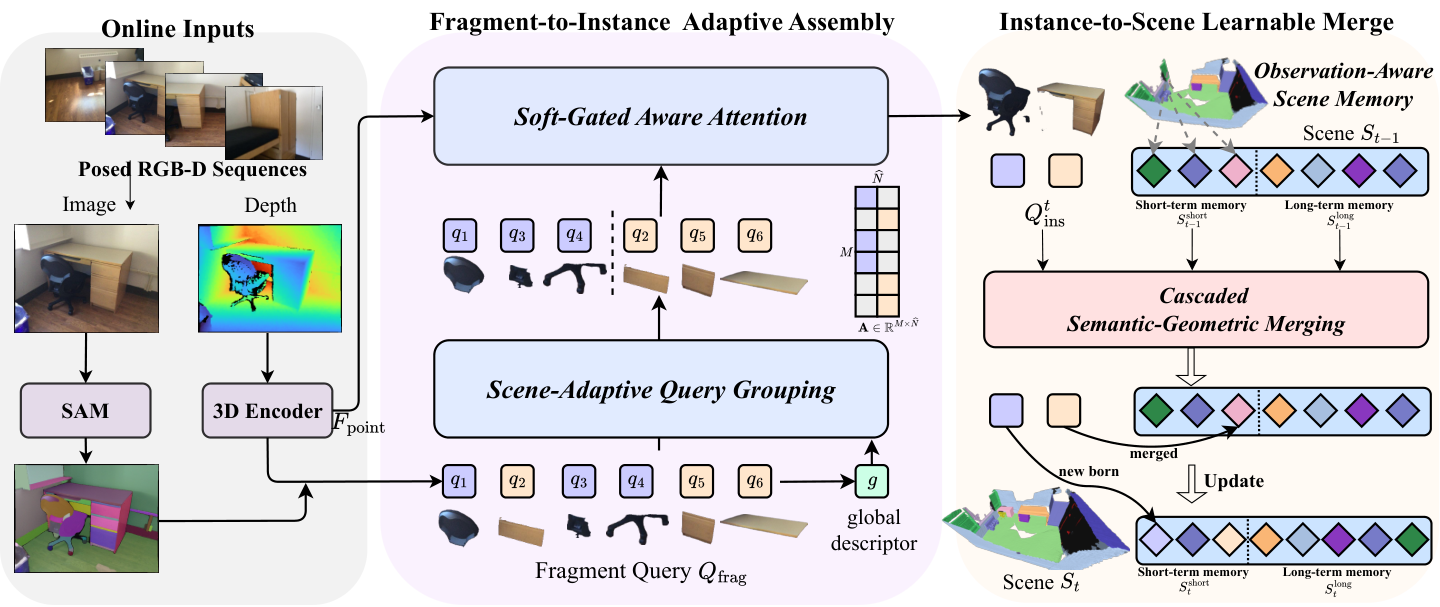
SAMosaic3D decomposes online open-vocabulary 3D segmentation into two learnable stages: Fragment-to-Instance Adaptive Assembly groups SAM-derived fragments into coherent instance queries, and Instance-to-Scene Online Merging associates instances with a persistent scene memory across frames. Both stages are jointly trainable end-to-end with hierarchical supervision.
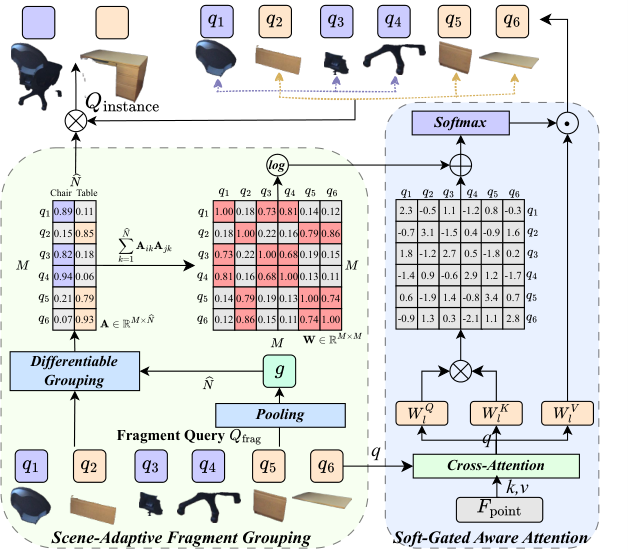
Scene-adaptive grouping predicts instance count and generates a differentiable co-instance affinity matrix. Soft-gated attention enables intra-instance fragments to aggregate complementary information while suppressing inter-instance interference.
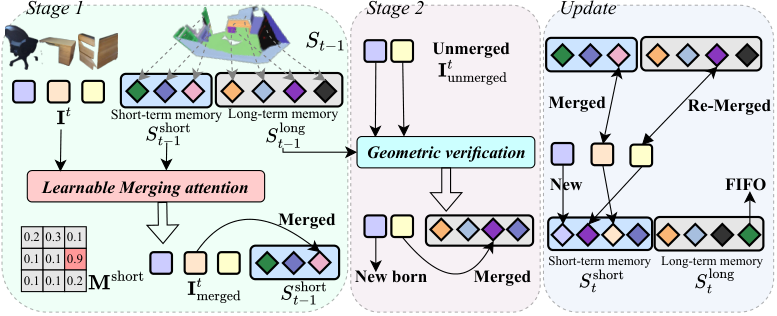
A two-tier memory partitions scene context into short-term and long-term tiers. Current instances merge via learnable cross-attention for incomplete observations, with geometric verification against long-term memory using 3D IoU.
Within-dataset evaluation on ScanNet and SceneNN validation sets.
| Method | ScanNet | SceneNN | ||||
|---|---|---|---|---|---|---|
| AP | AP50 | AP25 | AP | AP50 | AP25 | |
| Offline methods | ||||||
| TD3D | 46.2 | 71.1 | 81.3 | -- | -- | -- |
| OneFormer3D | 59.3 | 78.8 | 86.7 | -- | -- | -- |
| Online methods | ||||||
| INS-Conv | -- | 57.4 | -- | -- | 57.6 | -- |
| TD3D-MA | 39.0 | 60.5 | 71.3 | 26.0 | 42.8 | 59.2 |
| ESAM-E† | 41.6 | 60.1 | 75.6 | 27.5 | 48.7 | 64.6 |
| ESAM-E+FF†‡ | 42.6 | 61.9 | 77.1 | 33.3 | 53.6 | 62.5 |
| AutoSeg3D† | 43.4 | 62.5 | 77.4 | 33.1 | 52.6 | 63.8 |
| SAMosaic3D (Ours) | 45.3 | 65.9 | 78.5 | 33.2 | 56.5 | 69.3 |
| SAMosaic3D† (Ours) | 46.5 | 67.7 | 80.1 | 35.1 | 58.2 | 71.8 |
Class-agnostic 3D instance segmentation on ScanNet200 validation set.
| Method | VFM | AP | AP50 | AP25 | FPS |
|---|---|---|---|---|---|
| Offline methods | |||||
| SAMPro3D | SAM | 18.0 | 32.8 | 56.1 | -- |
| SAI3D | SemanticSAM | 28.2 | 47.2 | 67.9 | -- |
| Online methods | |||||
| SAM3D | SAM | 20.2 | 35.7 | 55.5 | 0.4 |
| ESAM | SAM | 42.2 | 63.7 | 79.6 | 0.7 |
| ESAM-E | FastSAM | 43.4 | 65.4 | 80.9 | 10.6 |
| AutoSeg3D | SAM | 45.5 | 66.7 | 81.0 | 0.7 |
| AutoSeg3D-E | FastSAM | 46.2 | 67.9 | 81.7 | 10.1 |
| SAMosaic3D (Ours) | SAM | 46.1 | 68.5 | 84.2 | 0.7 |
| SAMosaic3D (Ours) | FastSAM | 48.7 | 69.3 | 85.4 | 11.2 |
Zero-shot cross-dataset generalization from ScanNet200 (no fine-tuning on target domains).
| Method | ScanNet200 → SceneNN | ScanNet200 → 3RScan | ||||
|---|---|---|---|---|---|---|
| AP | AP50 | AP25 | AP | AP50 | AP25 | |
| Offline methods | ||||||
| SAMPro3D | 12.6 | 25.8 | 53.2 | 3.9 | 8.0 | 21.0 |
| SAI3D | 18.6 | 34.7 | 65.7 | 8.1 | 16.9 | 37.0 |
| Online methods | ||||||
| SAM3D | 15.1 | 30.0 | 51.8 | 6.2 | 13.0 | 33.9 |
| ESAM | 28.8 | 52.2 | 69.3 | 14.1 | 31.2 | 59.6 |
| ESAM-E† | 28.6 | 50.4 | 71.0 | 13.9 | 29.4 | 58.8 |
| AutoSeg3D | 29.7 | 53.6 | 71.9 | 16.0 | 32.4 | 60.7 |
| AutoSeg3D-E† | 30.2 | 54.1 | 72.8 | 16.8 | 34.3 | 61.0 |
| SAMosaic3D (Ours) | 31.7 | 56.8 | 74.2 | 16.3 | 34.7 | 63.1 |
| SAMosaic3D† (Ours) | 32.4 | 57.8 | 74.7 | 17.0 | 35.5 | 63.7 |
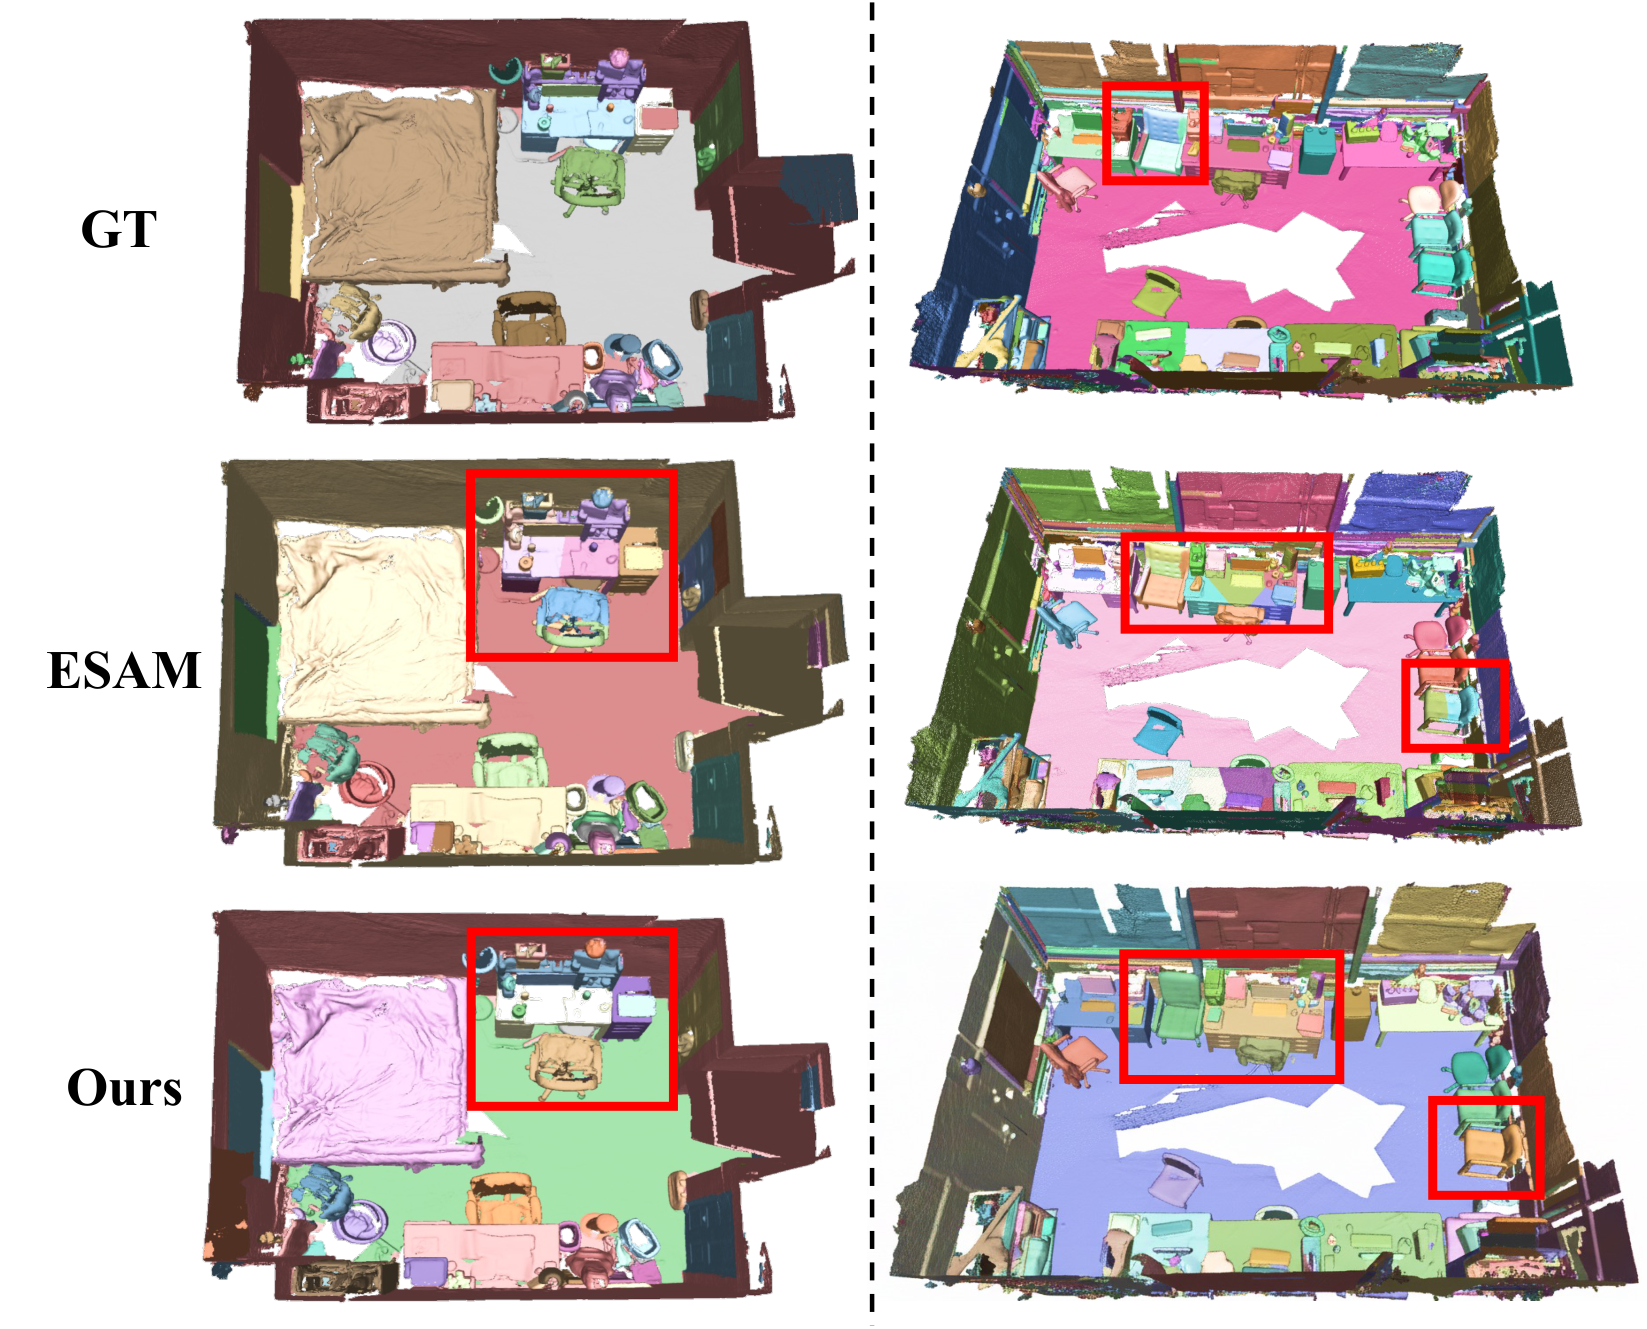
Qualitative comparison of 3D instance segmentation on challenging indoor scenes from SceneNN dataset. SAMosaic3D eliminates over-segmentation artifacts through differentiable soft assignment and co-instance affinity modeling.
@inproceedings{wang2026samosaic3d,
  title     = {SAMosaic3D: Modular Scene Assembly for Real-Time 3D Segment Anything},
  author    = {Wang, Peng and Wang, Yongcai and Chen, Wang and Cao, Hualong and Yang, Kang and Li, Chunxu and Jie, Wen and Li, Deying},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year      = {2026}
}